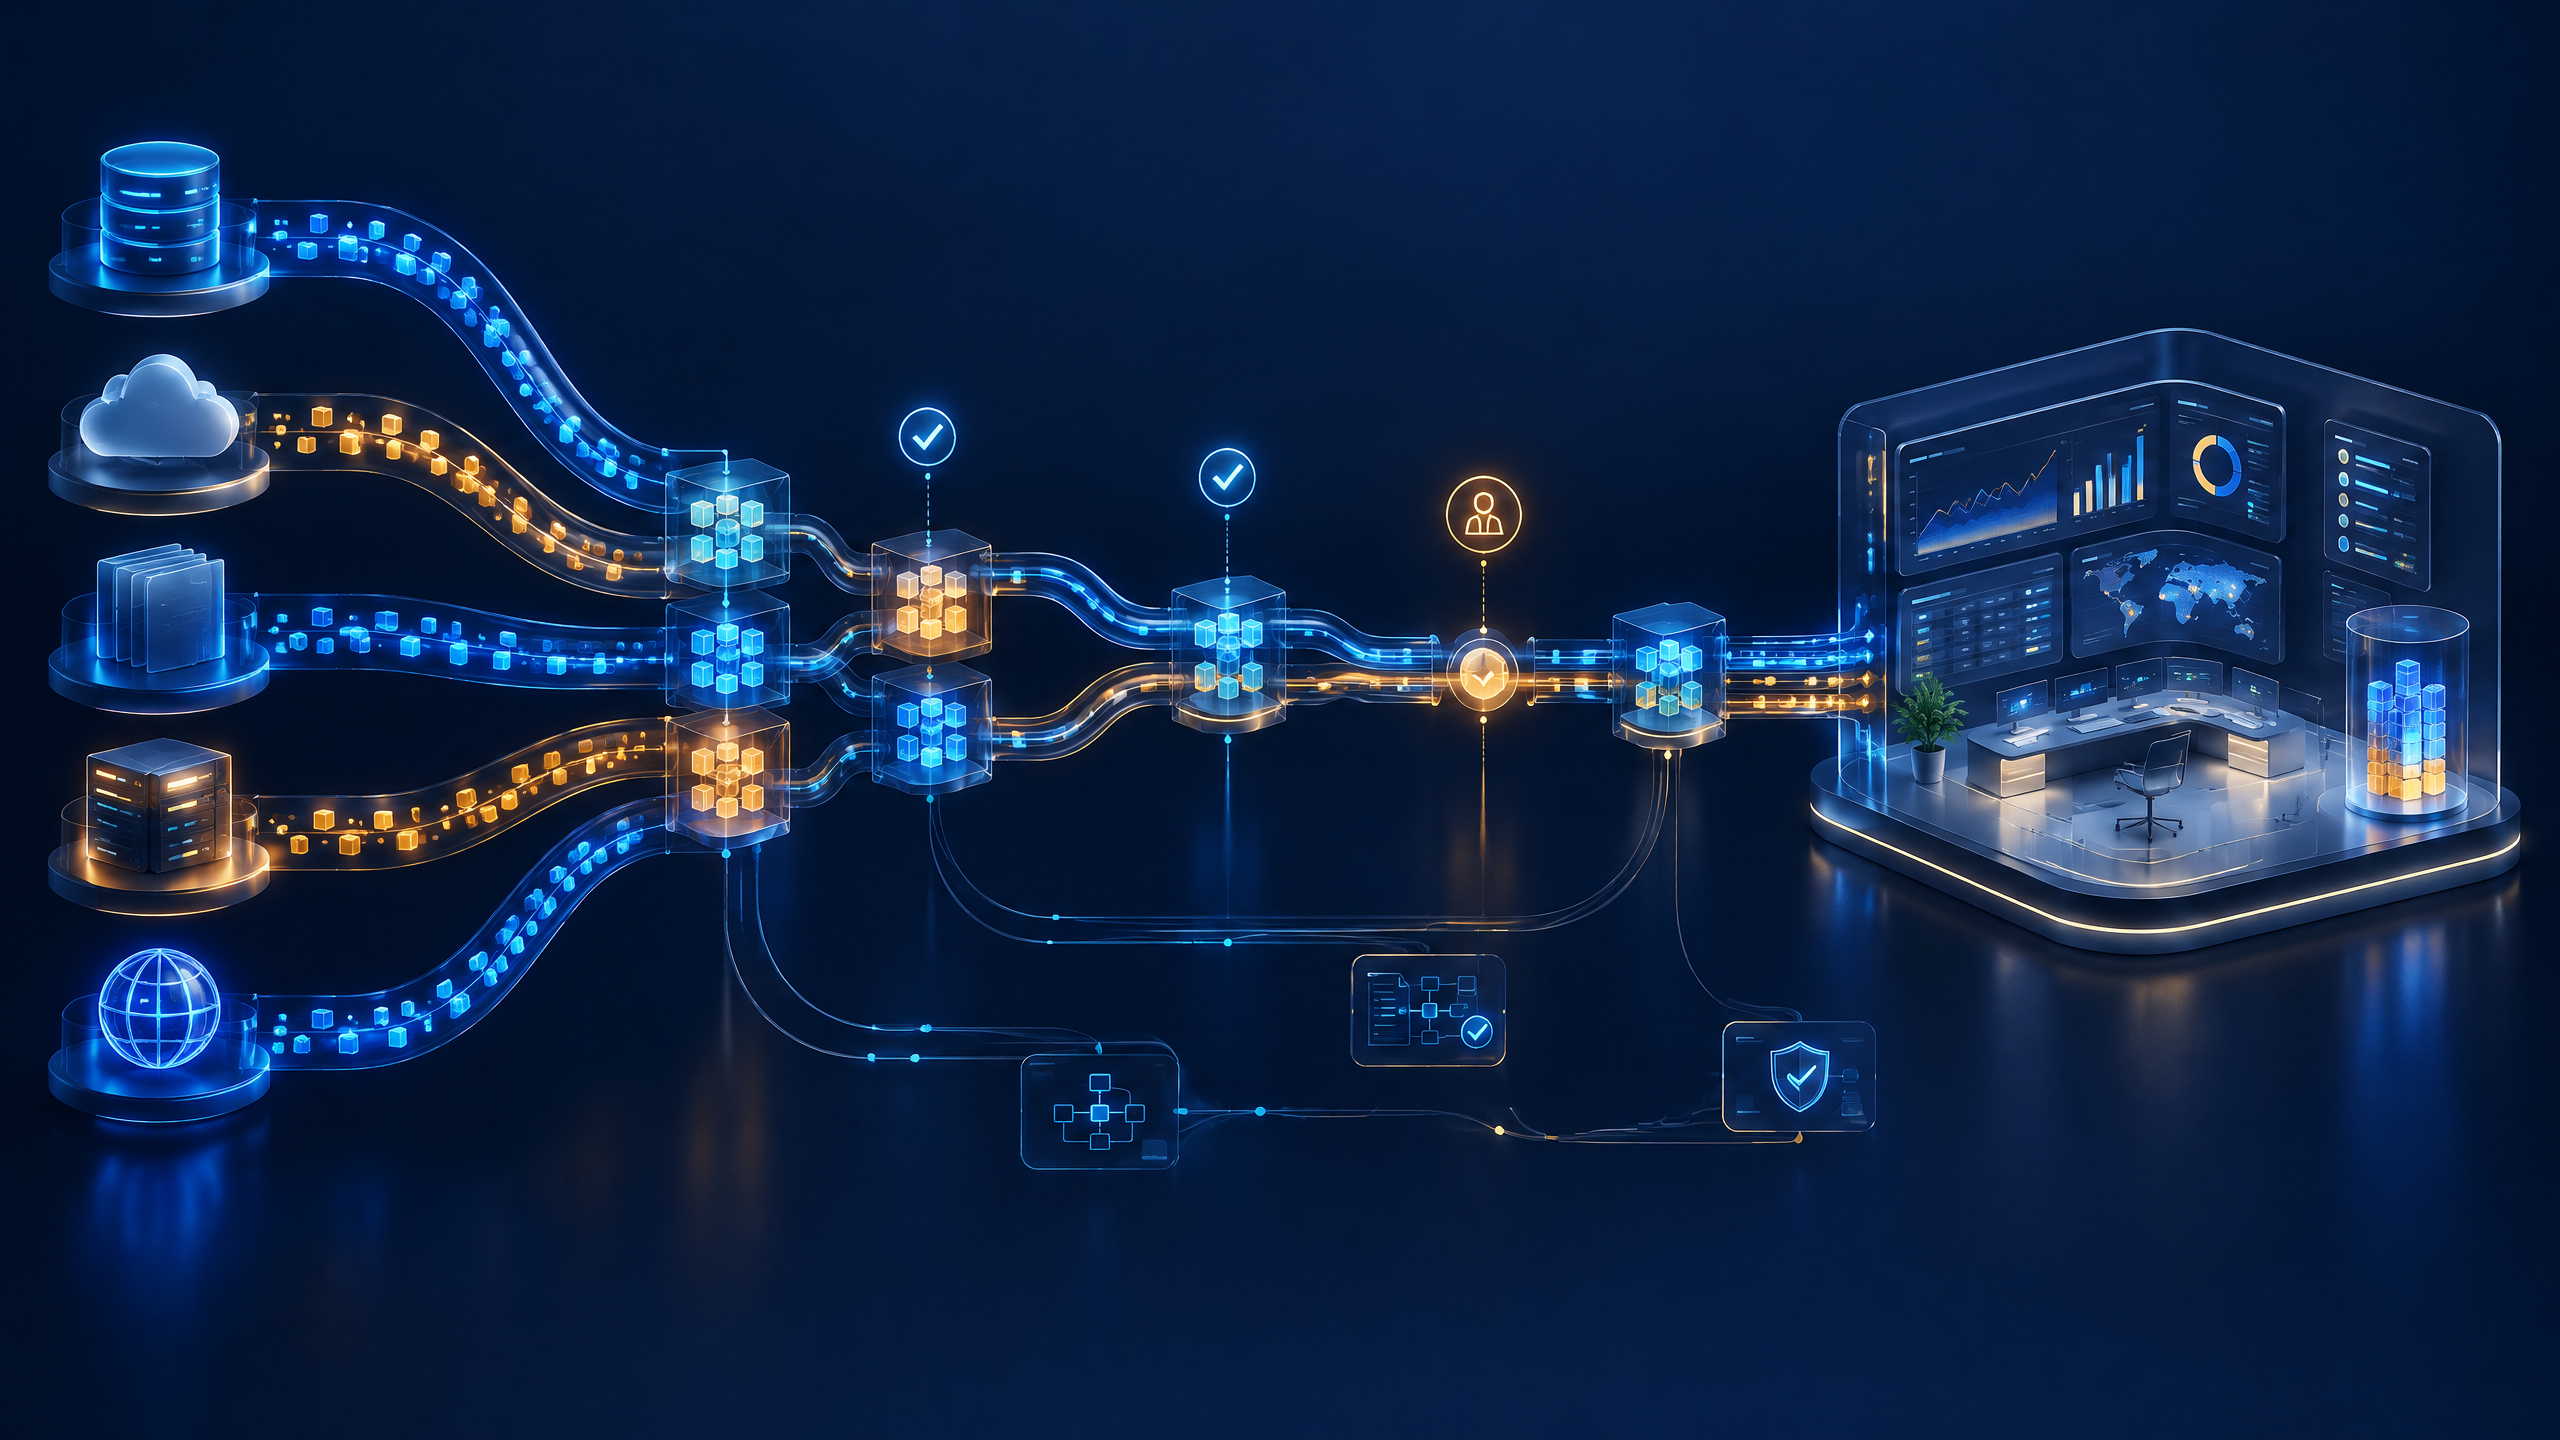
Etl Pipelines rarely win a board meeting, yet they often decide whether automation is trusted after its first difficult week. A founder may see a useful sales dashboard, a support agent with a confident answer and a different customer status in the CRM. The visible tools look separate; the underlying problem is usually the same: data has moved between systems without a clear, repeatable and observable route.
Extract, transform and load (ETL) takes data from defined sources, applies explicit rules and publishes it for a downstream report, webstack or agent. It is the operating layer that turns event records into business inputs. Without it, faster automation can amplify duplicates, stale statuses and undocumented assumptions.
Why Etl Pipelines are a business reliability problem
A growing firm commonly holds parts of the same commercial reality in several places: enquiries in a website form, opportunities in a CRM, invoices in finance software, delivery milestones in a project tool and conversations in a shared inbox. Each system is useful for its own job. None automatically provides a single definition of an active client, qualified lead, overdue invoice or completed engagement.
The practical failure is often quiet. A pipeline may join records on a changeable email address, convert a blank value into zero, refresh one source before another, or count a customer twice after a merger. A dashboard can still look polished. An AI agent can still write a plausible briefing. But the number, recommendation or message is now based on a premise that neither user can inspect easily.
This matters more where personal data travels through the flow. The ICO says organisations should take reasonable steps to make it accurate, record its source and status, update it where necessary, and correct or erase inaccurate or misleading information without delay.2 This is not an argument for every dataset to be perfect; it is an argument for visible purpose, provenance and correction paths where a record informs an important conversation or decision.
The UK Government Data Quality Framework makes the wider operational point: quality should be assessed through the lifecycle, communicated to users, and addressed at source rather than papered over with temporary fixes.1 For an operations leader, that converts a vague concern about “bad data” into ownership of an identifiable business process.
The mechanism: a useful ETL design preserves meaning
A reliable pipeline begins with a deliberately narrow question: what decision or service needs this data, and what can it safely mean? The answer defines the contract before a connector is selected.
Extract should capture records from named systems with a known time window, schema and access boundary. Retain the source identifier, collection time and version or watermark. Pulling “whatever is newest” complicates investigation when the source changes mid-run.
Transform makes business meaning explicit: standardising dates, mapping product names, deduplicating contacts, joining accounts to opportunities, excluding test records and classifying a lifecycle stage. These rules should be reviewable as code or configuration, not buried in a spreadsheet or agent prompt. It should also separate facts from derived fields: “invoice due date from finance system” is not “at-risk customer”, which may be a defined operational judgement.
Load publishes a controlled dataset, view or API for a named use. It should expose a stable grain—for example, one row per account per day—and state freshness expectations. It is not permission to overwrite history blindly; a records model may need to preserve corrections and status changes.
Apache Airflow’s guidance illustrates the reliability principle: treat tasks like database transactions, avoid incomplete results, design re-runs to produce the same outcome, use upserts rather than duplicate-producing inserts, and read and write specific partitions.3 The lesson applies whether a firm uses Airflow, managed integration software or a bespoke webstack: a retried run must not quietly create a second truth.
Controls that make ETL recoverable rather than fragile
Automation becomes dependable through a small set of operational controls, not through a claim that a pipeline cannot fail. First, define validation checks at the points where errors are costly: required fields, type and format checks, valid reference values, duplicate rates, row-count movements and reconciliation to the source total. Thresholds should reflect the use case; a small variance in anonymous web analytics has a different consequence from a missing customer record in a service workflow.
Second, make failure visible and safe. Quarantine rejected rows with a reason, alert the accountable owner, and avoid presenting a partial replacement as complete. Retain run logs, input and output counts, rule versions and approvals for material changes. These controls allow the team to diagnose a variance without reconstructing an incident from memory.
Third, record lineage. OpenLineage describes an open standard that records metadata for jobs in execution, using a generic model of datasets, jobs and runs.4 A firm does not need to adopt that standard to gain the benefit of the idea: an owner should be able to trace a dashboard field or agent input back to its source and transformation rule. Lineage makes a challenge actionable: “Why is this client marked inactive?” can lead to a particular source record and run, rather than to a general debate about the tool.
Finally, test changes as production changes. Airflow recommends treating DAGs as production-level code with associated tests.3 For smaller teams, use sample-record tests, a parallel run, reconciliation before release and a documented rollback. The aim is recoverability and evidence, not ceremony.
Where governed AI agents belong after the pipeline
AI agents can add useful work once the underlying data product has a defined boundary. For example, a customer-success coordinator may need a concise account brief built from a curated account view, current delivery milestones and approved knowledge articles. An agent can assemble that context, identify missing fields, draft a summary and route exceptions to the responsible person. It should not silently decide that a billing dispute is resolved, rewrite a source record because a narrative sounds credible, or become the only place where the business logic lives.
The safer design is to give the agent read access to a purpose-built, documented dataset or tool, rather than direct and unrestricted access to every operational system. Prompts can require it to distinguish source facts from suggestions, cite the supplied record identifiers, say when data is missing or stale, and escalate cases outside its authority. The ETL layer determines what is supplied; the agent helps people interpret or action work within that boundary.
This arrangement fits the intent of NIST’s voluntary AI Risk Management Framework, designed to incorporate trustworthiness considerations into the design, development, use and evaluation of AI systems.5 In practice, governance means naming the workflow owner, approved sources, decision rights, review route and monitoring measures before an agent influences a customer, employee or commercial process. Source quality, implementation choices and operating discipline remain decisive; an agent cannot repair hidden ambiguity.
A six-step decision sequence for founders and COOs
Use this sequence to turn a broad automation ambition into a bounded delivery conversation:
- Choose one operational decision. Start with a concrete question, such as which open opportunities require a follow-up this week. Name the user and the consequence of a wrong answer.
- Write the data contract. Define the source systems, record grain, mandatory fields, business definitions, freshness requirement and exclusions. Assign an accountable business owner—not only a technical maintainer.
- Build for replay. Use a stable run window or watermark, explicit transformations, idempotent writes and a route for late-arriving or rejected records. Preserve enough run evidence to compare outcomes.
- Validate and reconcile. Test representative edge cases, compare totals with the source, monitor completeness and set an escalation route for anomalies. Fix recurring defects at their originating process where possible.1
- Expose a narrow interface. Publish the resulting dataset only to the dashboard, webstack component or agent task that needs it. Grant the least access compatible with the job, and distinguish factual fields from calculated signals.
- Keep judgement accountable. Set the human approval point for high-impact messages or changes, review real exceptions and update rules when the business process changes. A pipeline is a living operational asset, not a one-off integration.
The sequence is deliberately unglamorous. Its value is that it establishes what the automation can know, what it may do, and when it must stop. That lets a firm expand from one trustworthy workflow rather than inherit a tangle of connectors whose results nobody owns.
Start with the data that already affects a customer or commercial decision
A sensible first scope is one recurring report or hand-off that creates friction: the weekly pipeline review, delivery-risk list, lead-qualification queue or client briefing. Map fields backwards to their sources, agree the definition of a complete record, and implement the smallest observable ETL that supports it. Only then decide whether a governed agent or webstack experience would make the result easier to use.
Neuro-Performance AI designs governed data flows, webstacks and agent workflows around that sequence, with specialist input on approved sources, challenge-testing, escalation design and ongoing improvement. The appropriate architecture depends on the quality of the source data, workflow ownership and the controls the team can operate. To discuss one bounded use case, request an architecture audit. You can also review how the service works before the conversation.
Sources
Sources
- [1]The Government Data Quality Framework — UK Government (Central Digital and Data Office)
- [2]Principle (d): Accuracy — Information Commissioner’s Office
- [3]Best Practices — Apache Airflow
- [4]About OpenLineage — OpenLineage / LF AI & Data Foundation
- [5]AI Risk Management Framework — National Institute of Standards and Technology
Next step
Request an architecture audit
A free 30-minute review of where AI agents and a connected webstack could remove work from your business — checked by our MBA and PhD experts.
Request an architecture audit